APPLICATION & PLATFORM MANAGED SERVICES
Keep your platform supported, accountable and ready to improve.
RedEx provides managed services for digital experience platforms, ecommerce and custom applications.
We combine operational assessment, hands-on engineering and ongoing maintenance to keep your platform supported, resolve recurring issues and plan improvements around your business priorities.
Clarify ownership
Define who handles incidents, dependencies and escalation.
Retain operational knowledge
Document environments, known issues and recovery steps.
Prioritise recurring problems
Connect support work with a risk-ranked improvement backlog.
Plan maintenance
Agree release, patching and validation responsibilities.
WHEN THIS SERVICE FITS
When platform support needs clearer ownership.
Incidents move between vendors. Critical knowledge sits with a few people. Updates wait because nobody has time to test them. Or a live application needs to move from its current provider without losing the knowledge required to operate it.
RedEx helps define who owns the work, what needs attention first and how the platform will be maintained. Responsibilities are agreed across your team, RedEx and other providers.
Support scope
What our managed services cover.
The agreement identifies the applications, environments and integrations covered. Monitoring hours, response commitments and improvement capacity are defined for that scope.
01 /
Application support
Triage incidents, investigate faults, implement agreed fixes and coordinate with system owners.
Keep escalation and communication responsibilities clear when several providers are involved.
02 /
Platform maintenance
Plan platform and dependency updates, test affected functions and support approved releases.
Address agreed vulnerabilities and technical debt within the supported application scope.
03 /
Monitoring & performance
Configure relevant alerts and review application health, performance and recurring incidents.
Connect findings to an owner and follow-up action.
04 /
Continuous improvement
Maintain a prioritised backlog for reliability, usability and operational efficiency.
Agree which changes fit the service capacity and which need separate project scope.
Technology expertise
Support from teams who understand the platform.
RedEx combines technology-agnostic advice with deep expertise in Adobe Experience Manager, Sitecore, Acquia/Drupal, WordPress, ecommerce and custom applications.
We assess the actual platform, version, extensions, hosting environment and integrations before defining the support model.
01 / DXP & CMS
Digital experience & content platforms
Support publishing workflows, custom components, platform updates and the integrations connecting content with other systems.
02 / MARKETPLACE
Ecommerce & connected applications
Investigate issues across the agreed customer journeys and application interfaces. Clarify which commerce, payment, product-data and third-party dependencies each provider supports.
03 / CUSTOM APPS
Custom application engineering
Trace recurring faults into the application, assess technical debt and implement agreed remediation. Plan changes with testing, documentation and release responsibilities.
Delivery lifecycle
From operational strategy to ongoing maintenance.
01 /
Assess & plan
Review platform health, dependencies, known issues and business-critical journeys. Agree responsibilities, service priorities and a risk-ranked improvement plan.
OUTPUTS
Service scope, readiness findings, ownership map and transition plan.
02 /
Transition & stabilise
Transfer agreed access and knowledge, establish monitoring and support channels, validate operating procedures and address priority issues within scope.
OUTPUTS
Access inventory, runbooks, escalation paths and transition acceptance checks.
03 /
Maintain & improve
Operate the agreed service, manage updates and releases, review recurring problems and prioritise improvements with your team.
OUTPUTS
Service reporting, maintenance plan and an agreed improvement backlog.
Transition and service boundaries
Establish the baseline before responsibility changes hands.
Illustrative deliverable: a service readiness pack
Document the applications, environments, integrations and access owners. Map critical user journeys to monitoring and a response owner. Record known issues, recovery procedures and unresolved risks so both teams can assess readiness for transition.
- Supported systems and dependency map
- Access, documentation and known-issue inventory
- Incident ownership and escalation contacts
- Release, rollback and recovery responsibilities
- Transition acceptance criteria and open risks
What the service agreement must define
Coverage hours, contact channels and severity levels
Response targets and restoration responsibilities
Maintenance windows, release approvals and exclusions
Infrastructure, licence and third-party responsibilities
Reporting cadence and improvement capacity
Documentation, access and knowledge transfer at exit
Monitoring, acknowledgement, restoration and permanent resolution are different service commitments. Availability targets apply to the systems and conditions defined in the agreement.
Technical and operating considerations
Separate monitoring coverage, acknowledgement time, restoration targets and feature-development capacity in the agreement. The first service review should examine recurring incidents and user impact alongside ticket volumes.
Relevant engagement
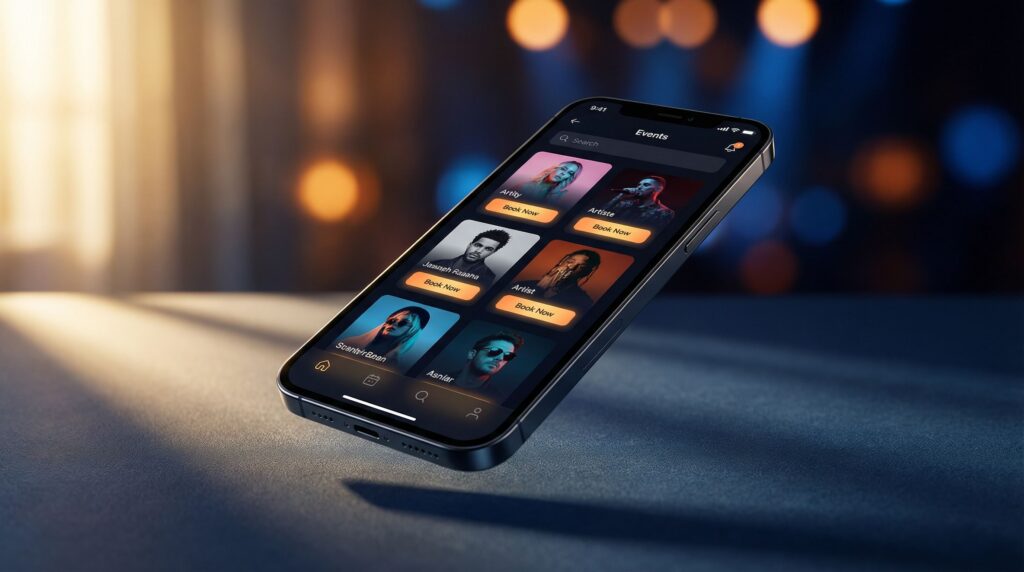
Taking over a live marketplace application
The published EventBooking engagement describes a transition from a previous vendor, combining application remediation, cloud consolidation and knowledge transfer with ongoing support. Its application stack included Flutter, VueJS, Node.js and MongoDB.
- PREMIUM Case Study
BUYING QUESTIONS
Before you choose a managed services partner.
What are managed services?
Managed services provide ongoing responsibility for an agreed technology scope. For RedEx, that can include application support, platform maintenance, monitoring and planned improvement, with responsibilities and service commitments defined in the agreement.
What is included in managed IT services?
The agreement identifies supported applications, environments, service hours, incident handling, maintenance and reporting. Response and restoration targets, exclusions and improvement capacity are defined for that scope rather than assumed across every engagement.
Can you take over a platform built by another provider?
Yes, subject to a readiness assessment. We review architecture, access, documentation, dependencies and known issues, then agree the transfer of knowledge and operational responsibilities.
Is round-the-clock support included?
Coverage is agreed for the supported platform. Monitoring, incident response and engineering support may have different schedules; they should be specified separately rather than assumed to be available around the clock.
What happens during a critical incident?
The agreed incident process defines severity, the response owner, escalation contacts and communication cadence. Recovery may involve RedEx, your team or another provider, depending on the affected system and access responsibilities.
Are feature changes included?
Minor improvements may be delivered through agreed service capacity. Larger features, migrations or architecture changes are assessed and scoped separately so routine support and project work have clear priorities.
Does every engagement include AIOps or automated remediation?
No. Automation is selected where reliable operating data, repeatable actions and appropriate controls support it. Monitoring and support do not require autonomous remediation. Any automated action needs agreed permissions, validation and recovery arrangements.
What is AIOps and how does it reduce IT operational costs?
AIOps (AI for IT Operations) refers to the application of machine learning and AI to IT operations data: monitoring alerts, log files, incident records, and performance metrics. The primary value is noise reduction and predictive capability.
Modern enterprise IT environments generate thousands of monitoring alerts per day, most of which are duplicates, false positives, or low-severity events that do not require human intervention. AIOps correlates these alerts, suppresses the noise, and surfaces only the signals that require action, reducing alert volume by 70% or more.
The secondary value is prediction: AIOps models trained on historical incident data can identify the pattern signatures that precede known incident types and trigger automated remediation before the incident impacts users.
In practice, organisations implementing AIOps-driven managed services see 25 to 45% reductions in IT operational costs within 12 months, primarily through reduced manual handling time and fewer escalations to senior engineers.
How long does transition take, and what determines cost?
Platform complexity, documentation, access, technical debt, coverage and required remediation determine the effort. The proposal separates transition work, recurring support, third-party costs and additional development.
One partner from the next decision through ongoing operation
Bring your priorities, current platforms and the stage where you need support. We can start with strategy, take on implementation or maintain and improve an existing application. Each engagement defines its scope and responsibilities.